
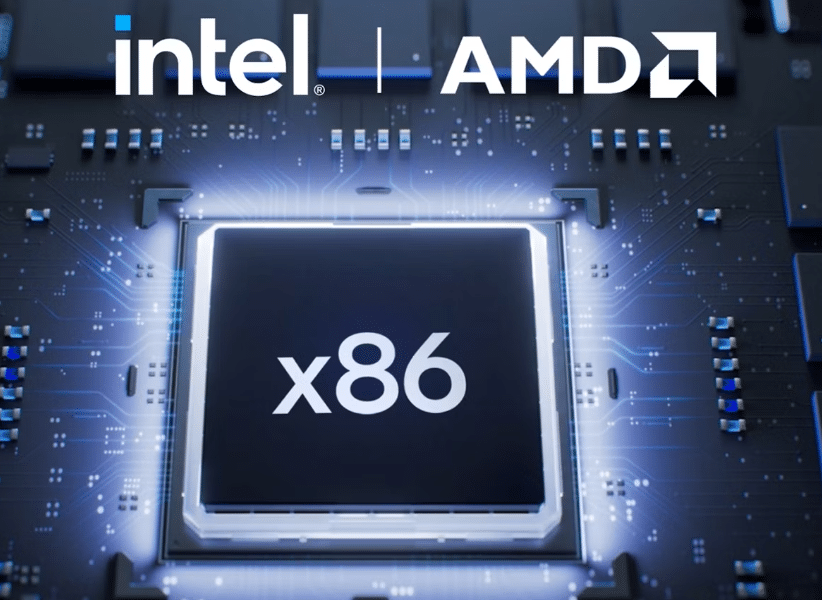
AMD and Intel are aligning open-source CPU optimisations for PyTorch through oneDNN, aiming to simplify AI software development, improve portability and support accelerated neural-network workloads across x86 processors.
AMD and Intel are bringing their CPU optimisation technologies closer together through the open-source oneAPI Deep Neural Network Library (oneDNN), aiming to simplify artificial intelligence (AI) development with the PyTorch framework across x86-based computing platforms. The collaboration combines AMD’s ZenDNN optimisations with oneDNN, providing developers with a shared software foundation for accelerating deep-learning workloads on processors from both manufacturers.
For open-source electronics developers, the move addresses a key challenge in deploying AI on general-purpose processors: software must efficiently use each processor’s computing architecture without requiring developers to maintain separate optimisation paths. A common library could reduce integration effort and make AI applications easier to build and deploy across different x86 systems.
PyTorch is widely used to develop and run machine-learning models, including neural networks used for image recognition, language processing and inference. These workloads depend heavily on operations such as matrix multiplication and convolution, which process large amounts of numerical data. The oneDNN library provides optimised implementations of these operations, helping applications use available CPU computing resources more efficiently.
AMD’s ZenDNN technology is designed to optimise AI workloads on its Zen-based processors, including EPYC server CPUs. Incorporating these optimisations into oneDNN is intended to make architecture-specific improvements accessible through a common software interface. The library is an open-source project supported by the Unified Acceleration Foundation (UXL), which focuses on developing portable software for accelerated computing.
The companies are also working on AI Compute Extensions (ACE), a proposed extension to the x86 instruction set architecture (ISA) designed to accelerate matrix multiplication. These operations are central to neural-network training and inference. Integrating support for such instructions into software libraries could allow developers to access processor-level acceleration without implementing low-level routines independently.
The collaboration follows a recommendation from the x86 Ecosystem Advisory Group. AMD has also joined the UXL Foundation as a steering member, supporting the development of open-source tools for heterogeneous computing.
For embedded systems engineers, hardware designers and AI developers, shared optimisation libraries could make CPU-based inference easier to integrate into edge computing and industrial systems. However, the extent of the performance gains will depend on implementation, processor architecture and software support. Neither company has announced quantified performance improvements or a definitive timeline for completing the integration.