
A small 7-billion parameter language model that employs hybrid attention and sparse activations to provide accelerated AI inference with lower memory usage.
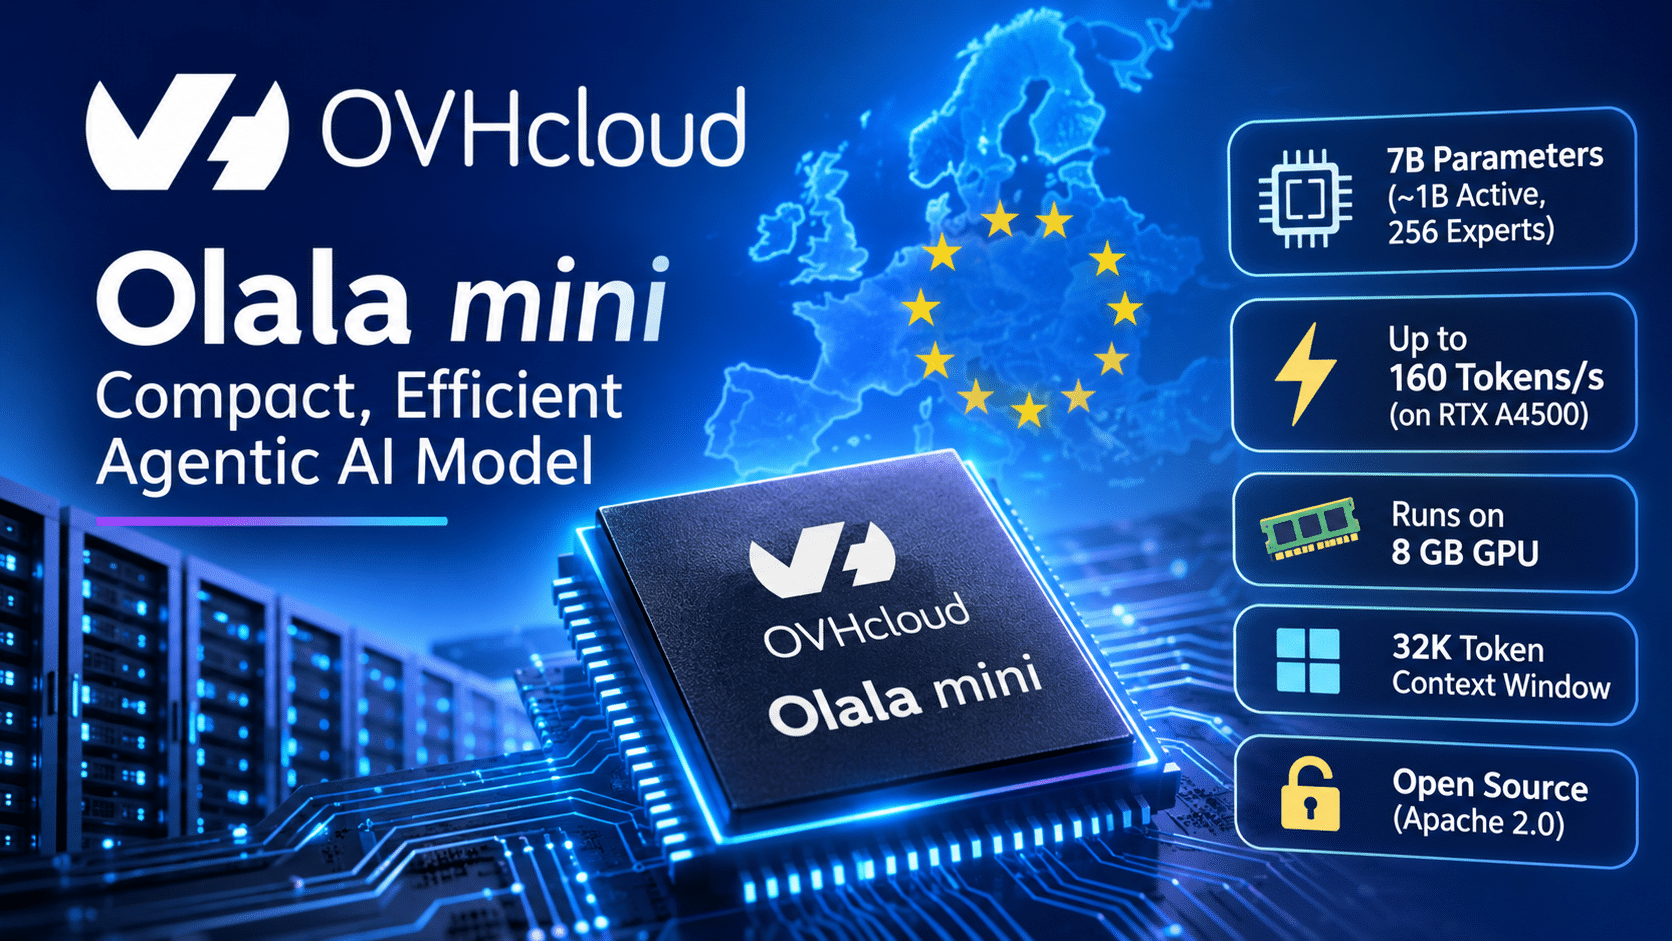
The European cloud computing company OVHcloud has launched Olala mini 7A1B, which is the first family of LLMs from the company, and features hybrid attention designed to decrease computational and memory resources needed for AI systems. The architecture of the model relies on a combination of differential-TPA and Mamba-3 attention and mixture-of-experts architecture.
Olala mini contains seven billion parameters, having approximately one billion active parameters divided among 256 experts per layer. While the entire model is not used in all requests, some of the parameters only activate within the architecture of the model, thus reducing the computational and memory load. Working in BF16 format, it supports a maximum context window size of 32,000 tokens and runs on 8 GB of GPU memory. According to OVHcloud, the inference speed is 160 tokens per second on NVIDIA RTX A4500 GPU and 50 tokens per second on a simple CPU without GPU.
The training of Olala was done on three European public supercomputers, which include Jupiter, MeluXina, and Jean Zay supercomputers that use NVIDIA GH200, A100, and H100 GPUs respectively. The total value of the computational resources utilized during training amounts to approximately €7 million in European public support. It also helped in the creation of OVHcloud’s Agentic Lab, OVHai LLM.Olala mini has already been incorporated in the flash answer tool by the search engine company Qwant and according to reports, it is offering 20% faster answers with a reduction in operating costs by three times compared to the previous version used.
OVHcloud has made plans to make Olala mini open source on Hugging Face using the Apache 2.0 license, along with model weights, its base model, technical report, and documentation for compliance with AI Act. The new version Olala 1.1, which is due by the end of 2026, will have an increased context window to 128,000 tokens and improved mathematical reasoning. Olala 2.0 which is to follow, will have more than 100 billion parameters and is aimed at Enterprise agentic AI, cloud DevOps, and cybersecurity. Such models are also designed to run on local AI systems on workstations through OVHai Workspace. CEO Octave Klaba mentioned how easily available it has become to train LLMs with significantly reduced training costs.